hycusampling — Uniform sampling of the unit hypercube
This module provides functions for super-uniform sampling of the unit hypercube. ‘Super-uniform’ in this context means that the obtained point sample is more uniform than a random uniform sample, which is a desirable property in many applications. After creation, the samples can be transformed from the unit hypercube to arbitrary cuboids.
Sampling algorithms
Stratified sampling
- diversipy.hycusampling.stratify_conventional(num_strata, dimension)
Stratification of the unit hypercube.
This algorithm divides the hypercube into num_points subcells and draws a random uniform point from each cell. Thus, the result is stochastic, but more uniform than a random uniform sample. For further information see [McKay1979].
- Parameters:
- Returns:
strata – As the strata are axis-aligned boxes in this case, each tuple in the returned list contains the lower and upper corner of a stratum.
- Return type:
- diversipy.hycusampling.stratify_generalized(num_strata, dimension, cuboid=None, detect_special_case=True, avoid_odd_numbers=True)
Generalized stratification of the unit hypercube.
The adjective “generalized” pertains to the fact that the number of strata can be chosen arbitrarily, which is not possible with
stratify_conventional(). It is guaranteed that all strata have volumevolume(cuboid) / num_strata, apart from rounding error.- Parameters:
num_strata (int) – The number of strata to generate. An arbitrary number of points is possible for this algorithm.
dimension (int) – The dimension of the search space.
cuboid (tuple of list, optional) – Optionally specify the hypercube to be sampled in. If None, the unit hypercube is chosen.
detect_special_case (bool, optional) – If True,
num_points ** (1/dimension)is integer, and we are sampling the unit cube, use the original stratified sampling instratify_conventional().avoid_odd_numbers (bool, optional) – If this value is True, splits are chosen so that the resulting numbers are even, whenever possible. E.g., if a stratum with six points is splitted, it is not split into three and three, but two and four points. For more information on this option, see [Wessing2018].
- Returns:
strata – As the strata are axis-aligned boxes in this case, each tuple in the returned list contains the lower and upper corner of a stratum.
- Return type:
References
[Wessing2018] (1,2)Wessing, Simon (2018). Experimental Analysis of a Generalized Stratified Sampling Algorithm for Hypercubes. arXiv eprint 1705.03809. https://arxiv.org/abs/1705.03809
- diversipy.hycusampling.stratified_sampling(strata, bates_param=1, latin='none', matching_init='approx', full_output=False)
Stratified sampling with given strata.
- Parameters:
strata (list of tuple) – The strata to be sampled. Each tuple in the list must contain the lower and upper corner of a stratum.
bates_param (int, optional) – Each coordinate of a point sampled in a stratum is determined as the mean of this number of independent random uniform variables. Thus, the coordinates follow the Bates distribution.
latin (str, optional) – Indicates if and how the point set should be latinized. “none” is the fastest option, sampling the points in linear time without latinization. “approx” uses a heuristic with runtime
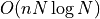 that may produce a slightly imperfect
latinization. “matching” produces an error-free latinization using
a maximum cardinality matching algorithm with runtime
 . The union of the strata must be the unit hypercube
for the second and third option to work.
matching_init (str, optional) – This is an additional option to the setting
latin == "matching". Firstly, the approximative latinization fromlatin == "approx"can be used as initialization for the matching algorithm, with the matching acting as a repair method if necessary. This is the recommended choice due to its favorable runtime behavior. The other two options use a problem-agnostic greedy initialization. “greedy-rand” randomly shuffles the edges in the bipartite graph data structure. This order indirectly influences the distribution of the point sample, via the deterministic matching algorithm. “greedy-det” is the deterministic variant without extras, which may produce patterns due to the deterministic nature of the algorithm.full_output (bool, optional) – Indicates if the indices of points with latin hypercube violations are returned in case of latinized sampling.
- Returns:
points (numpy array) – The sampled points, in corresponding order to strata.
error_indices (set) – Indices of points with violations of the latin hypercube property in some dimension. Can only be non-empty for
latin == "approx".
- diversipy.hycusampling.reconstruct_strata_from_points(points, cuboid=None)
Partitions the cuboid so that each point has its own hyperbox.
This partitioning is stochastic (ties are broken randomly). The obtained strata will have different volumes. This function can be used to calculate an upper bound for the covering radius of arbitrary point sets via
covering_radius_upper_bound(). The idea for this approach was introduced in [Wessing2018].- Parameters:
- Returns:
strata – As the strata are axis-aligned boxes in this case, each tuple in the returned list contains the lower and upper corner of a stratum. The order corresponds to the order of points.
- Return type:
Latin hypercube designs
- diversipy.hycusampling.lhd_matrix(num_points, dimension)
Generate a random latin hypercube design matrix.
Latin hypercube designs sometimes give an advantage over random uniform samples due to their perfect uniformity of one-dimensional projections. For further information see [McKay1979]. This algorithm has linear run time.
- Parameters:
- Returns:
design – Matrix with integers corresponding to the bins of a virtual grid. Each column consists of a permutation of {0, …, num_points - 1}.
- Return type:
(num_points, dimension) numpy array
References
- diversipy.hycusampling.improved_lhd_matrix(num_points, dimension, num_candidates=100, target_value=None, dist_matrix_function=None)
Generate an ‘improved’ latin hypercube design matrix.
This implementation uses an algorithm with quadratic run time. It is a greedy construction heuristic starting with a randomly chosen point. In each iteration, a number of random candidates is evaluated by a criterion that considers a candidate’s distance to the previously chosen points. The best point according to this criterion is included in the LHD. The concept originally stems from [Beachkofski2002]. The algorithm implemented here was proposed in [Wessing2015].
- Parameters:
num_points (int) – The number of points to generate.
dimension (int) – The dimension of the space.
num_candidates (int, optional) – The number of random candidates considered for every point to be added to the LHD.
target_value (float, optional) – The distance a candidate should ideally have to the already chosen points of the LHD.
dist_matrix_function (callable, optional) – Defines the distance used. Default is Manhattan distance on a torus (maximum distance is
num_points - 1, well-suited foredge_lhs()).
- Returns:
design – Matrix with integers corresponding to the bins of a virtual grid. Each column consists of a permutation of {0, …, num_points - 1}.
- Return type:
(num_points, dimension) numpy array
References
[Beachkofski2002]Beachkofski, B.; Grandhi, R. (2002). Improved Distributed Hypercube Sampling. American Institute of Aeronautics and Astronautics Paper 1274.
- diversipy.hycusampling.has_lhd_property(design_matrix)
Check if design matrix has the LHD property.
It is assumed that counting starts from zero and points are arranged row-wise. So, each column must consist of a permutation of
range(num_points).- Parameters:
design_matrix (array_like) – 2-D array of integer coordinates.
- Returns:
is_lhd
- Return type:
Lattices
- diversipy.hycusampling.rank1_design_matrix(num_points, dimension, generator_vector=None)
Design matrix for a rank-1 lattice.
This algorithm is deterministic and has linear run time.
- Parameters:
- Returns:
design – Matrix with integers corresponding to the bins of a virtual grid.
- Return type:
(num_points, dimension) numpy array
- diversipy.hycusampling.korobov_design_matrix(num_points, dimension, generator_param=None)
Design matrix for a Korobov lattice.
This is a special case of the rank-1 lattice. The design has the LHD property if
gcd(num_points, generator_param) == 1. The algorithm is deterministic and has linear run time.- Parameters:
- Returns:
design – Matrix with integers corresponding to the bins of a virtual grid.
- Return type:
(num_points, dimension) numpy array
Other
- diversipy.hycusampling.maximin_reconstruction(num_points, dimension, num_steps=None, initial_points=None, existing_points=None, use_reflection_edge_correction=False, sampling_function=None, dist_matrix_function=None, callback=None)
Maximize the minimal distance in the unit hypercube with extensions.
This algorithm carries out a user-specified number of iterations to maximize the minimal distance of a point in the set to 1) other points in the set, 2) existing (fixed) points, and 3) the boundary of the hypercube. Details can be found in [Wessing2015].
- Parameters:
num_points (int) – The number of points to generate.
dimension (int) – The dimension of the space.
num_steps (int, optional) – The number of iterations to carry out. Default is
100 * num_points.initial_points (array_like, optional) – The point set to improve (if None and sampling_function`is None, too, a sample is drawn with :func:`stratified_sampling, otherwise sampling_function is used to generate it or the given set is used).
existing_points (array_like, optional) – Points that cannot be modified anymore, but should be considered in the distance computations.
use_reflection_edge_correction (bool, optional) – If True, selection pressure in boundary regions will be increased by considering additional distances to virtual points, which are created by mirroring the real points at the boundary.
sampling_function (callable, optional) – A function producing one candidate point in the unit hypercube per call. It can be used to introduce some kind of non-uniform sampling. Must accept dimension as input argument. Default is random uniform sampling.
dist_matrix_function (callable, optional) – The function to compute the distances. Default is Manhattan distance on a torus.
callback (callable, optional) – If provided, it is called in each iteration with the current point set as argument for monitoring progress.
- Returns:
points
- Return type:
(num_points, dimension) numpy array
References
[Wessing2015] (1,2)Wessing, Simon (2015). Two-stage Methods for Multimodal Optimization. PhD Thesis, Technische Universität Dortmund. http://hdl.handle.net/2003/34148
- diversipy.hycusampling.random_k_means(num_points, dimension, num_steps=None, initial_points=None, dist_matrix_function=None, callback=None)
MacQueen’s method.
In its default setup, this algorithm converges to a centroidal Voronoi tesselation of the unit hypercube. Further information is given in [MacQueen1967].
- Parameters:
num_points (int) – The number of points to generate.
dimension (int) – The dimension of the space.
num_steps (int, optional) – The number of iterations to carry out. Default is
100 * num_points.initial_points (array_like, optional) – The point set to improve (if None, a sample is drawn with
stratified_sampling()).dist_matrix_function (callable, optional) – The function to compute the distances. Default is Euclidean distance.
callback (callable, optional) – If provided, it is called in each iteration with the current point set as argument for monitoring progress.
- Returns:
cluster_centers
- Return type:
(num_points, dimension) numpy array
References
[MacQueen1967]MacQueen, J. Some methods for classification and analysis of multivariate observations. Proceedings of the Fifth Berkeley Symposium on Mathematical Statistics and Probability, Volume 1: Statistics, pp. 281–297, University of California Press, Berkeley, Calif., 1967. http://projecteuclid.org/euclid.bsmsp/1200512992.
- diversipy.hycusampling.halton(num_points, dimension, skip=0)
Generate a Halton point set.
Quasirandom sequence using the default initialization with the first dimension prime numbers.
- diversipy.hycusampling.random_uniform(num_points, dimension)
Syntactic sugar for
numpy.random.rand().
- diversipy.hycusampling.grid(num_points, dimension)
Create conventional grid in unit hypercube.
Also related to full factorial designs.
- diversipy.hycusampling.sukharev_grid(num_points, dimension)
Create Sukharev grid in unit hypercube.
Special property of this grid is that points are not placed on the boundaries of the hypercube, but at centroids of the num_points subcells. This design offers optimal results for the covering radius regarding distances based on the max-norm.
Helper functions
- diversipy.hycusampling.unitcube(dimension)
Shortcut to generate a tuple of bounds of the unit hypercube.
- diversipy.hycusampling.scaled(points, from_cuboid, to_cuboid)
Linear transformation between arbitrary cuboids.
This function does not check if the points are actually inside from_cuboid.
- Parameters:
- Returns:
scaled_points – A new array containing the scaled points.
- Return type:
numpy array
- diversipy.hycusampling.transform_perturbed(design_matrix)
Transform a design matrix into a sample in the unit hypercube.
Applies random perturbations so that each point is distributed randomly uniform in its grid cell. This is the variant proposed by [McKay1979]. It is not checked if design_matrix is a LHD.
- Parameters:
design_matrix (array_like) – Array containing integers to indicate the bins occupied by each point.
- Returns:
points
- Return type:
(num_points, dimension) numpy array
- diversipy.hycusampling.transform_cell_centered(design_matrix)
Transform a design matrix into a sample in the unit hypercube.
Each point is placed at the centroid of a subcell in the assumed grid over the cube. It is not checked if design_matrix is a LHD.
- Parameters:
design_matrix (array_like) – Array containing integers to indicate the bins occupied by each point.
- Returns:
points
- Return type:
(num_points, dimension) numpy array
- diversipy.hycusampling.transform_spread_out(design_matrix)
Transform a design matrix into a sample in the unit hypercube.
The transformation is so that each face of the hypercube is sampled by at least one point (exactly one point in the case of LHDs). Use this transformation if you want to maximize the minimal distance between points in the design. It is not checked if design_matrix is a LHD.
- Parameters:
design_matrix (array_like) – Array containing integers to indicate the bins occupied by each point.
- Returns:
points
- Return type:
(num_points, dimension) numpy array
- diversipy.hycusampling.transform_anchored(design_matrix)
Transform a design matrix into a sample in the unit hypercube.
This is typically used with rank-1 lattices. The zero-vector is a fix point in this transformation. It is not checked if design_matrix is a LHD. The highest value sampled is
(num_points - 1) / num_points. You may want to applyshifted_randomly()afterwards to get perturbation.- Parameters:
design_matrix (array_like) – Array containing integers to indicate the bins occupied by each point.
- Returns:
points
- Return type:
(num_points, dimension) numpy array
- diversipy.hycusampling.shifted_randomly(points)
Cranley-Patterson rotation.
- Parameters:
points (array_like) – 2-D array of points.
- Returns:
shifted_points – A new array containing the shifted points.
- Return type:
numpy array
References
[Cranley1976]R. Cranley; T. N. L. Patterson (1976). Randomization of Number Theoretic Methods for Multiple Integration. SIAM Journal on Numerical Analysis, vol. 13, no. 6, pp. 904-914.